
Casting a Mannequin: Turning Unreal's Quinn into Our Talent Miranda Calder
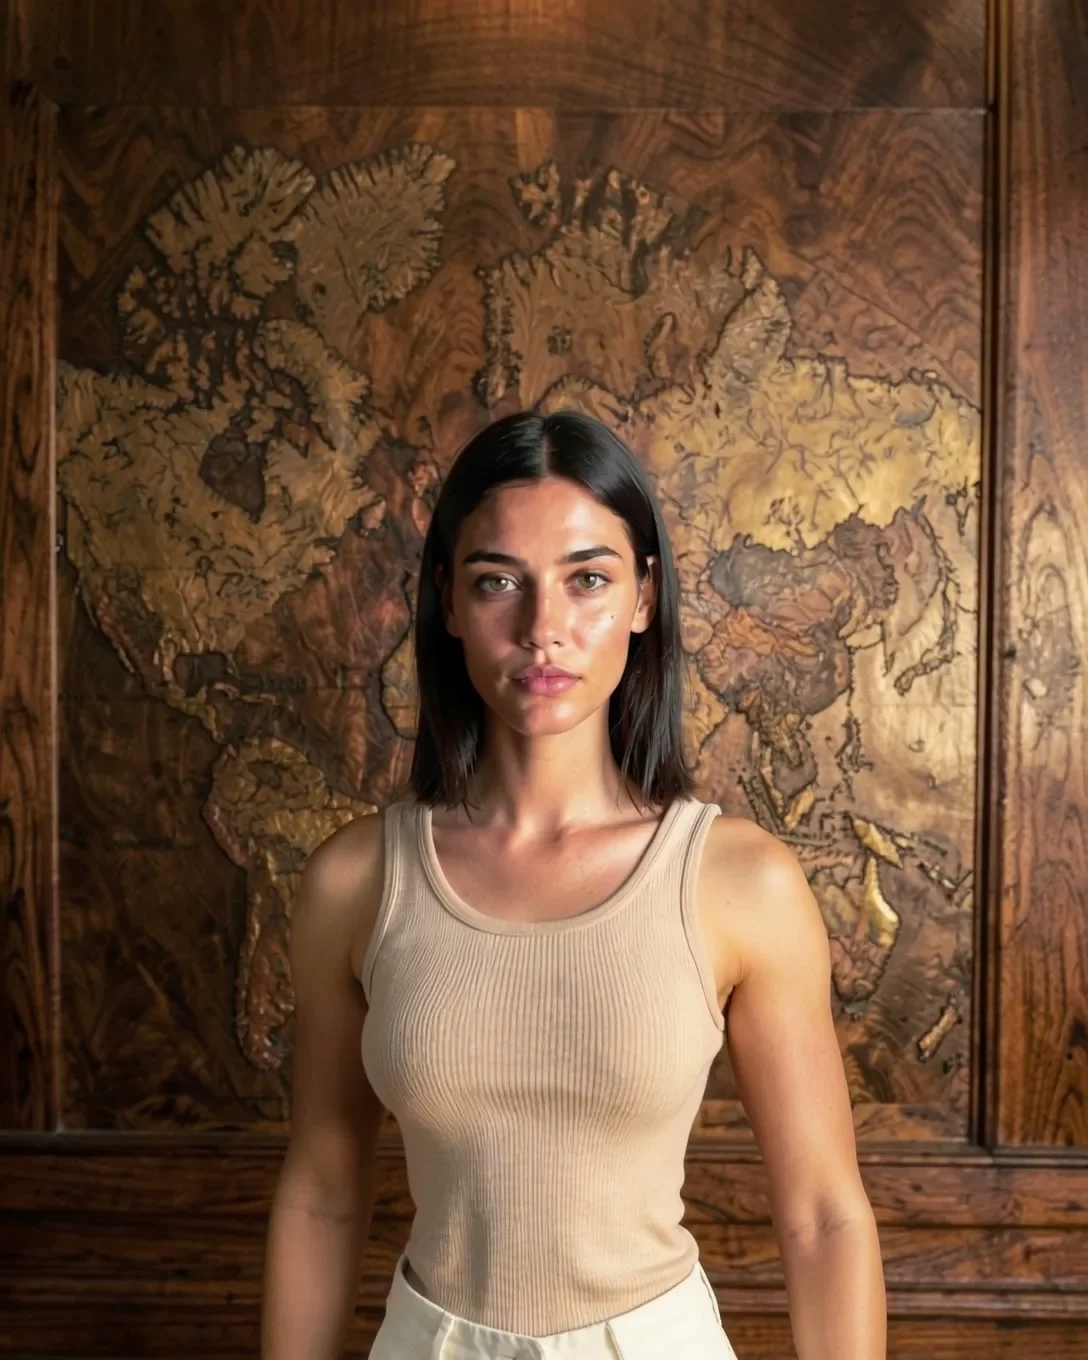
Unreal's stock mannequin gives us the body and the move; a look still and a head-crop faceswap give us the person. Cropping the head doubled the face's pixels and lifted identity from 6.5 to 8.5 out of 10.
Key takeaways
- Blocking: Unreal's Quinn mannequin with an idle animation, a 35 mm lens in portrait, camera at eye height, a linear push-in.
- Look still: an image-model edit of the grey frame (3 seeds, keep the one aligned to the layout), then a faceswap from Miranda's neutral front portrait.
- A full-frame faceswap put the face in at about 192 px and scored 6.5/10 in a blind A/B. A head-crop swap put it in at about 394 px and scored 8.5/10.
- Identity stability across 81 frames was 9/10 in both versions. The video model holds the look still, so the look still decides identity.
- An absolute 1–10 vision score rated both versions 7/10. Only the blind A/B separated them.
Why a mannequin, not a digital human
In our Unreal-to-AI pipeline (overview here), the video model repaints every surface from a single finished frame, the look still. That includes the face. So the character in Unreal does not need to look like anyone. It needs to stand in the right place, have the right proportions and move the right way.
That makes Unreal's stock mannequin, Quinn, a reasonable first choice. With an idle animation applied, she was in the scene in minutes. A fully detailed digital human is slower to set up and slower to render, and its face would be painted over anyway. Our rule was mannequin first, and a more realistic body only if the body read wrong. (It did, in one respect; see The Body Is the Brief.)
The talent here is Miranda Calder, one of OMNI's own synthetic models. She is AI-generated; no real person was filmed.
Blocking the shot
We framed a portrait shot on a 35 mm lens with a vertical filmback, camera at eye height, and a slow push-in toward the mannequin. On this lens in portrait, a standing person at 3 m is framed head to knee, which is a natural fashion framing.
The push-in uses linear keys, for the reason we measured in the zoom bug: eased keys read as the image rescaling itself. The mannequin stands in front of the carved map panel from the library set, so the room carries over from the earlier tests.
Building the look still
The look still starts as an image-model edit of the first grey frame. The prompt describes the finished person and room and insists that nothing moves: same pose, same edges, same perspective. The negatives rule out what the mannequin might drag in: robot, mannequin, armour, plastic, helmet, a changed pose.
Image models still recompose sometimes, so we run three seeds, overlay each on the grey frame, and keep the one that lines up. A look still that is slightly off the layout produces a clip that slides into place over the first frames.
Then we bind the person. The edited still has a plausible face but not Miranda's, so we faceswap from her neutral front portrait. The reference's head angle should match the target; a straight-on mannequin wants a straight-on portrait.
Full-frame vs head-crop faceswap
Our first version swapped the face on the full frame. In a head-to-knee portrait the face is small, and it went into the swap at about 192 px wide. The second version cropped the head and hair, upscaled the crop to 1024, swapped there, and feathered the result back into the frame. The face went in at about 394 px.
| Method | Face size going into the swap | Blind A/B | Identity stability over 81 frames |
|---|---|---|---|
| Full frame | about 192 px | 6.5/10 | 9/10 |
| Head crop | about 394 px | 8.5/10 | 9/10 |
The difference is in the specifics. Her freckles, hazel eyes and the mole on her cheek survived only in the head-crop version. The full-frame swap produced a similar woman; the crop produced Miranda.
The look still decides identity
The most useful number in that table is the one that did not change. Identity stability across all 81 frames was 9/10 in both versions. The video model held whatever face it was given, faithfully, from the first frame to the last.
That tells us where to spend effort. Identity is not lost in the video stage; it is set in the still. A better still gives a better clip, and a flawed still gives a flawed clip for every frame.
Score with A/B, not with a number
We first asked a vision model to score each version on an absolute 1–10 scale. It gave both 7/10. Shown the two side by side, blind, it separated them clearly: 8.5 against 6.5.
Absolute scores are too coarse to tell a good version from a better one. When the question is which of two versions to keep, ask that question directly.
The object that wasn't there
One defect had nothing to do with the face. A rectangular object kept entering from the left of the frame. It was not an AI invention: our level was built from an engine template, and its icons were sitting in the layout. Hiding 34 template actors in Unreal removed it.
The finished render took 4.5 minutes and cost $0. Next, the problem we did not solve with the face: the body. The Body Is the Brief: Why Our First AI Persona Came Out Muscular. Previous in the series: Where AI Video Forgets.
Related
Building a Room Out of Holograms: Empty Set, Wireframe, Solid
An empty place fills up as wireframe holograms that turn solid on a spoken word. We did it on a locked Unreal shot and on handheld AI footage, then spent three rounds killing the flicker.
The Snap Reveal: Why MiniMax H3 Ignored the Gesture and Unreal Didn't
A woman snaps her fingers and a choir appears behind her. A frame-to-frame video model kept her playing and faded the choir in like ghosts. Blocking the gesture in Unreal put it exactly where we wanted it.
A Wireframe Hologram Effect Built from Depth, Not Generated
One object turns into a glowing digital twin while everything else stays real. A text prompt picks the object, depth wraps the grid around its curves, and it rendered on the first try for $0.