
FastH3 Omni: Identity-Locked Persona Video on a Local GPU
FastH3 replaced WanGP Ref2VA on our local 16 GB workstation: render times dropped from 32 minutes to 5 minutes, dialogue followed the script, and 1088×1920 rendered direct.
Key takeaways
- FastH3 cuts 704×1280 render times from 32m 06s to 5m 31s cold and 4m 49s warm across 8 steps.
- Blind QA scored FastH3 at 9/10 on complex head turns and rooftop dialogue scenes where WanGP scored 1/10.
- Facial identity against reference stills scored 8/10, holding freckles and cheek moles cleanly across motion.
- Peak VRAM during 704×1280 inference is 15.6 GB with completely flat step times and zero memory thrashing.
- Direct 1088×1920 generation renders in 14m 55s with no compositional breakdown, producing sharper facial detail than 704×1280.
The Ref2VA bottleneck and the 8-step distillation
Running identity-locked reference-to-video on local consumer hardware was previously bottlenecked by two problems: excessive step counts and ignored prompts. WanGP Ref2VA required 20 steps and frequently ignored the scene environment and dialogue lines entirely. Generative diffusion engines often let conditioning latents overpower text guidance, causing character models to revert to generic positions regardless of prompt text. FastH3 Omni changes this baseline. It is FastVideo's full PDD+DMD distillation of MiniMax H3 Ref2VA, running on an isolated ComfyUI server on port 7835. It is not an experimental low-step LoRA; it is a separately trained student model that follows camera direction, scene staging, and spoken dialogue.
On Miranda at 704×1280 with 124 frames and 3 reference images, WanGP Ref2VA took 32m 06s across 20 steps, averaging ~90 s/step. FastH3 completed the same take in 5m 31s cold and 4m 49s warm across 8 steps, averaging ~25.5 s/step. That is a substantial reduction in wall-clock time on identical hardware, making iterative shot direction viable on a single local GPU workstation. Instead of waiting half an hour per iteration, a director can review takes within five minutes.
In high-volume commercial production, rendering latency dictates creative iteration. When a single generation requires over half an hour to produce five seconds of video, creative teams cannot explore multiple camera angles or lighting setups within a production day. Reducing turn-around time to under five minutes allows prompt engineers to evaluate character performances interactively while maintaining consistent hardware utilization.
Blind QA: scene adherence and facial identity retention
The speed improvement matters only because the model follows prompt direction. Under WanGP, reference conditioning routinely overpowered scene instructions. On a head-turn brief, WanGP failed blind QA: the character turned the wrong way and ended off-angle. FastH3 scored 9/10, executing a clean profile to front-on turn with the face centered in the final frame.
On a challenging rooftop plus spoken line test, WanGP scored 1/10 by discarding the prompt and rendering a generic white studio with zero mouth movement. FastH3 scored 9/10 on the identical brief: it rendered the specified rooftop, urban skyline, black slip dress, moving lips, and camera push-in. The distilled attention layers accurately separate identity conditioning from environmental staging cues.
| Metric / Test Brief | WanGP Ref2VA (20 steps) | FastH3 Omni (8 steps) | Performance Impact |
|---|---|---|---|
| Wall-clock (704×1280, 124 f) | 32m 06s | 5m 31s cold / 4m 49s warm | Significant speedup on local 16 GB hardware |
| Step time | ~90 s/step | ~25.5 s/step | Flat execution pace with zero memory thrashing |
| Head-turn brief QA | REJECT (turns wrong way, ends off-angle) | KEEP 9/10 (profile to front-on, face centered) | Follows camera and physical motion prompts |
| Rooftop + spoken line QA | REJECT 1/10 (white studio, no speech) | KEEP 9/10 (rooftop, skyline, black slip, speech) | Follows environmental scene staging |
| Identity fidelity vs ref | 7–8/10 | 8/10 | Preserves fine facial moles and freckles |
| Peak VRAM consumption | 10–15 GB | 15.6 GB | Fits within 16 GB RTX 5060 Ti budget |
Identity preservation scored 8/10. Miranda's facial structure, freckles, and signature cheek mole held consistently throughout the take without drifting into an average generic face. The model preserves fine epidermal features across dynamic facial rotation without requiring external post-generation face swapping.
VRAM envelope and runner graph architecture
Memory consumption on an RTX 5060 Ti 16 GB requires strict pipeline discipline. Peak VRAM during a 704×1280 generation reached 15.6 GB, operating right at the physical memory boundary, compared to 10–15 GB on the base model. Crucially, step times remained flat throughout the 8 steps without falling into system memory thrashing.
The runner script `fasth3_r2v.py` executes a dedicated ComfyUI graph using `BasicGuider` without CFG. It feeds reference images into `ref_images.ref_image_N` within the `MiniMaxH3ReferenceToVideo` node. The model was trained with block-sparse attention, so VSA must stay on; alternate attention mechanisms like sla and sol-attn are incompatible and cause generation failures.
The model files live on disk at `D:/AI/Flux3-ComfyUI/ComfyUI/models/`. The core unet checkpoint `fasth3_omniref_8step_pruned_int8_convrot` occupies 22.2 GB with 1098 tensors, paired with `minimax_h3_video_vae_fp16` and `minimax_h3_audio_vae_fp32`. The text encoder uses the NVFP4 format, sharing identical weights with WanGP. Because ComfyUI handles tensor offloading efficiently, all model blocks fit into active memory sequentially.
Operating close to the hardware ceiling requires strict memory isolation. Running the ComfyUI backend on a dedicated port separate from other image generation services prevents latent tensor fragmentation. When background processes leave uncollected CUDA allocations in memory, subsequent generation calls risk triggering out-of-memory faults during initial model weights loading.
Native 1088×1920 direct generation
WanGP thrash-locked whenever we attempted vertical high-definition renders. FastH3 handles direct 1088×1920 generation smoothly. In a UGC selfie test utilizing 5 reference images across 124 frames, direct 1088×1920 completed in 14m 55s, maintaining a steady pace of ~87 s/step.
While Windows task manager reported approximately 19 GB under shared GPU memory allocation, step times did not degrade. This memory profile reflects ComfyUI dynamic tensor staging rather than memory thrashing. Despite operating beyond the nominal 1 MP training resolution, the render exhibited zero body duplication, zero limb distortion, and no compositional collapse.
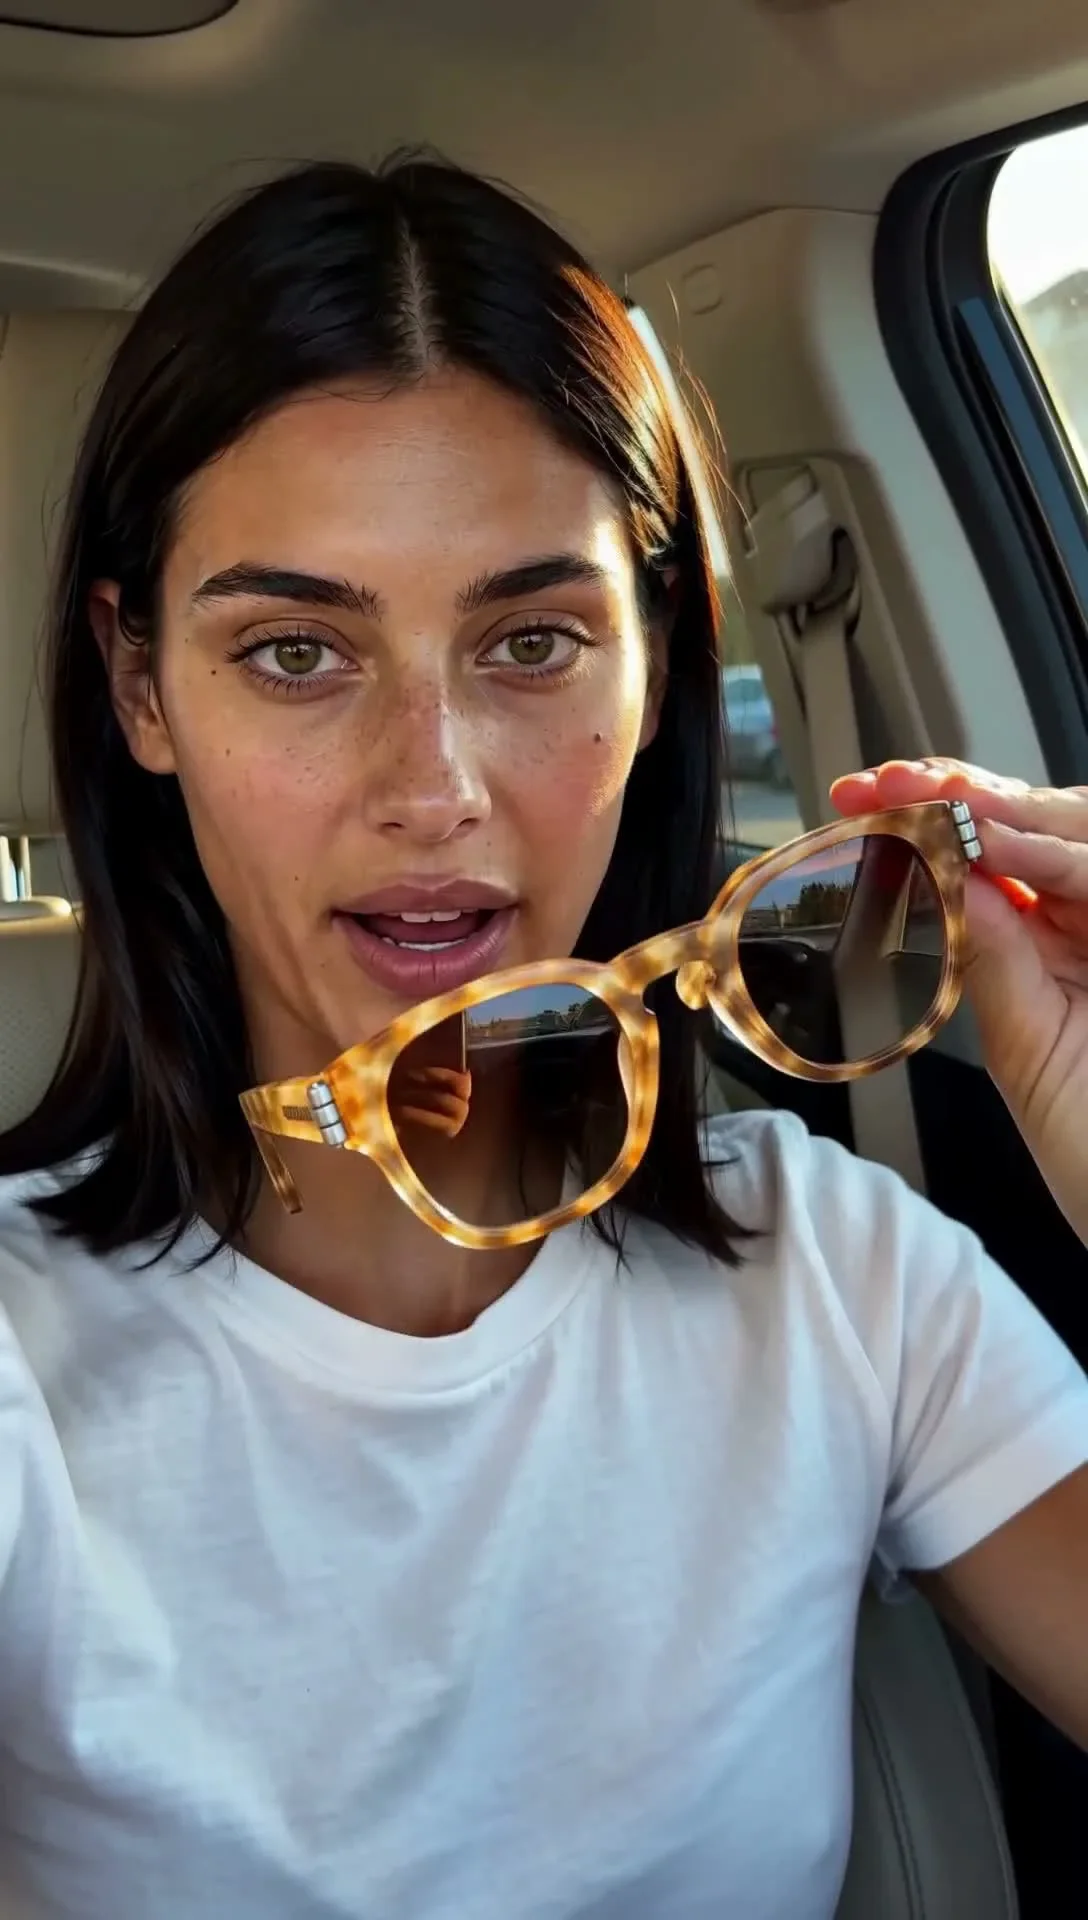
Direct 1088×1920 frames are visibly sharper than upscaled 704×1280 drafts. Individual brow hairs, skin pore structures, eyewear hinge screws, and reflections inside pupil catchlights resolve cleanly. When high-resolution commercial delivery is required, rendering direct at 1088×1920 avoids the plastic artifacts introduced by post-generation video upscalers, ensuring pristine texture fidelity across the clip.
Audio loudness quirks and seed sensitivity
FastH3 generates native audio alongside video frames, but acoustic amplitude varies dramatically by content type. In tests with spoken dialogue, speech audio rendered healthy levels at -23 dB. However, on prompts specifying quiet room tone and breath ambience, audio output came out near-silent at -65.7 dB mean volume, compared to -15.3 dB on the un-distilled base model.
Resolution changes also alter seed behavior. A seed evaluated at 704×1280 will produce a noticeably different performance take when re-rendered at 1088×1920. Production teams must use 704×1280 for rapid direction probes, and then generate fresh seed batches when moving to full-resolution delivery. Treating low-resolution drafts as structural proxies rather than pixel-identical previews keeps the workflow efficient.
Related
Dynamic Beat Splitting: Pacing and Dialogue in AI Micro-Dramas
Fixed four-clip templates destroy dramatic tension. Dynamic beat splitting tailors continuous takes from 4 to 30 s while strictly enforcing dialogue budgets.
The $0 UGC Ad Pipeline: Roster Personas, Voice, and Scale
How we produce local UGC selfie ads with synthetic talent: locking product scale through body ratios, eye-level framing, and JSON-linked voices.
Inside the Paper Wife Lookbook: Grade, Halation, Catchlights
Magnific Classic 2k hardened the eye catchlights on our upscales, so we wrote a fix. Here is the whole pipeline behind OMNI Lookbook Vol. 03, from 14 chat-generated frames to a 4:4:4 web edition.