
Staging AI Feet and Grounding: Kinematics and Inversion Traps
Prompting 'front foot planted' frequently leaves feet dangling over voids. Describing terrain placement rather than limb action solves grounding.
Key takeaways
- Dynamic kinematic descriptions like 'front foot planted, back heel lifted' frequently suffer semantic inversion, floating feet over drop-offs.
- Engineers must describe where limbs exist on physical surfaces rather than describing sequential anatomical action.
- Defining environmental voids as hazards situated strictly between both feet forces diffusion models to ground each foot on solid masonry.
- Impossible physical briefs—such as a 1m human stride leaping a 25m street—inevitably surface as downstream video generation defects.
- Integrating explicit conditional failure tests directly into prompt conditioning compels the text encoder to enforce spatial rules.
The spatial inversion trap of dynamic kinematic phrasing
Directing human locomotion in text-to-image diffusion models reveals a persistent blind spot in spatial reasoning. In complex fashion editorials where a talent strides across broken terrain or architectural ledges, prompt engineers instinctively reach for sequential kinematic instructions. We describe one foot stepping forward, weight transferring across the ball, and the trailing heel elevating into swing phase. In practice, multimodal attention mechanisms frequently decouple descriptive adjectives from their intended anatomical targets.
During production testing on our miranda_cigale_rooftop_v4 campaign, early iterations relied on classic kinematic framing. The prompt instructed: 'front foot planted, back heel lifted and swinging'. Rather than grounding the subject cleanly, the model inverted the spatial relationship. The generative output pinned the trailing foot to the background structure while extending the leading leg out over an empty urban canyon. The model understood that one foot should be planted and one should be elevated, but completely swapped which limb occupied which coordinate.
Never describe which foot is doing what action; describe where both feet are placed in physical space. When prompts rely on relative qualifiers like 'front' and 'back', rotational variance between camera perspectives and character orientation creates severe semantic drift. Replacing dynamic kinetic verbs with explicit spatial placements establishes an unambiguous coordinate system that prevents kinematic inversion across complex staging.
Defining environmental hazards between solid contact planes
Solving foot grounding requires restructuring prompt geometry from the ground up. In the revised miranda_cigale_rooftop_v4 prompt structure, we established a strict architectural rule: every limb instruction must anchor to a named, solid physical surface. The updated prompt explicitly declares that both feet are positioned firmly above solid roof blocks, eliminating any possibility of ambiguous limb suspension.
Crucially, the prompt redefines the spatial hazard. Instead of warning the model to avoid stepping into the void, the prompt frames the drop-off as a passive object trapped between two solid anchor points. The street gap is described as a narrow canyon lying entirely between the span of her stride. By defining the void as an entity bounded on both sides by structural masonry, the latent space is forced to materialize contiguous ground beneath both the leading toe and the trailing heel.
Furthermore, the prompt widens the physical landing pads. Specifying that each rooftop provides a broad, flat zinc surface several times wider than the talent's footwear gives the model sufficient latent territory to seat the sole. When environmental landing surfaces are prompted as narrow ledges, the model struggles to balance contact constraints, resulting in clipped heels and mangled ankles across rendered takes.
Injecting explicit conditional failure tests into conditioning
Diffusion models respond powerfully to negative conditional assertions when framed as structural quality thresholds. Alongside positive surface descriptions, the prompt integrates a hard programmatic assertion: 'if either foot hangs over a street, a courtyard, a rooftop edge or empty air, the image is wrong'. This formulation operates not as generic negative padding, but as an explicit rejection filter that penalizes latents featuring unsupported geometry.
| Prompt Strategy | Kinematic Description | Hazard Positioning | Observed Grounding Fidelity |
|---|---|---|---|
| Dynamic Action (v3) | 'Front foot planted, back heel lifted' | Unspecified drop-off | Inverted; leading foot floating over void |
| Negative Exclusion | 'No floating feet, no hovering shoes' | Global negative prompt | Ignored; artifacts cluster along edges |
| Spatial Anchor (v4) | 'Both feet over solid roof surfaces' | Hazard positioned between feet | Flawless; solid contact on zinc masonry |
| Conditional Rejection | Explicit 'if either foot hangs, image is wrong' | Paired with spatial anchors | Enforces strict contact shadows and alignment |
Placing grounding rules at the very top of the prompt hierarchy reinforces their semantic weight. When spatial instructions are buried beneath elaborate styling, fabric textures, and makeup descriptions, attention weights attenuate before reaching terrain constraints. Moving foot placement to the primary conditioning block ensures that the generative engine resolves physical support structures before decorating the character.
Resolving geometric impossibilities before video synthesis
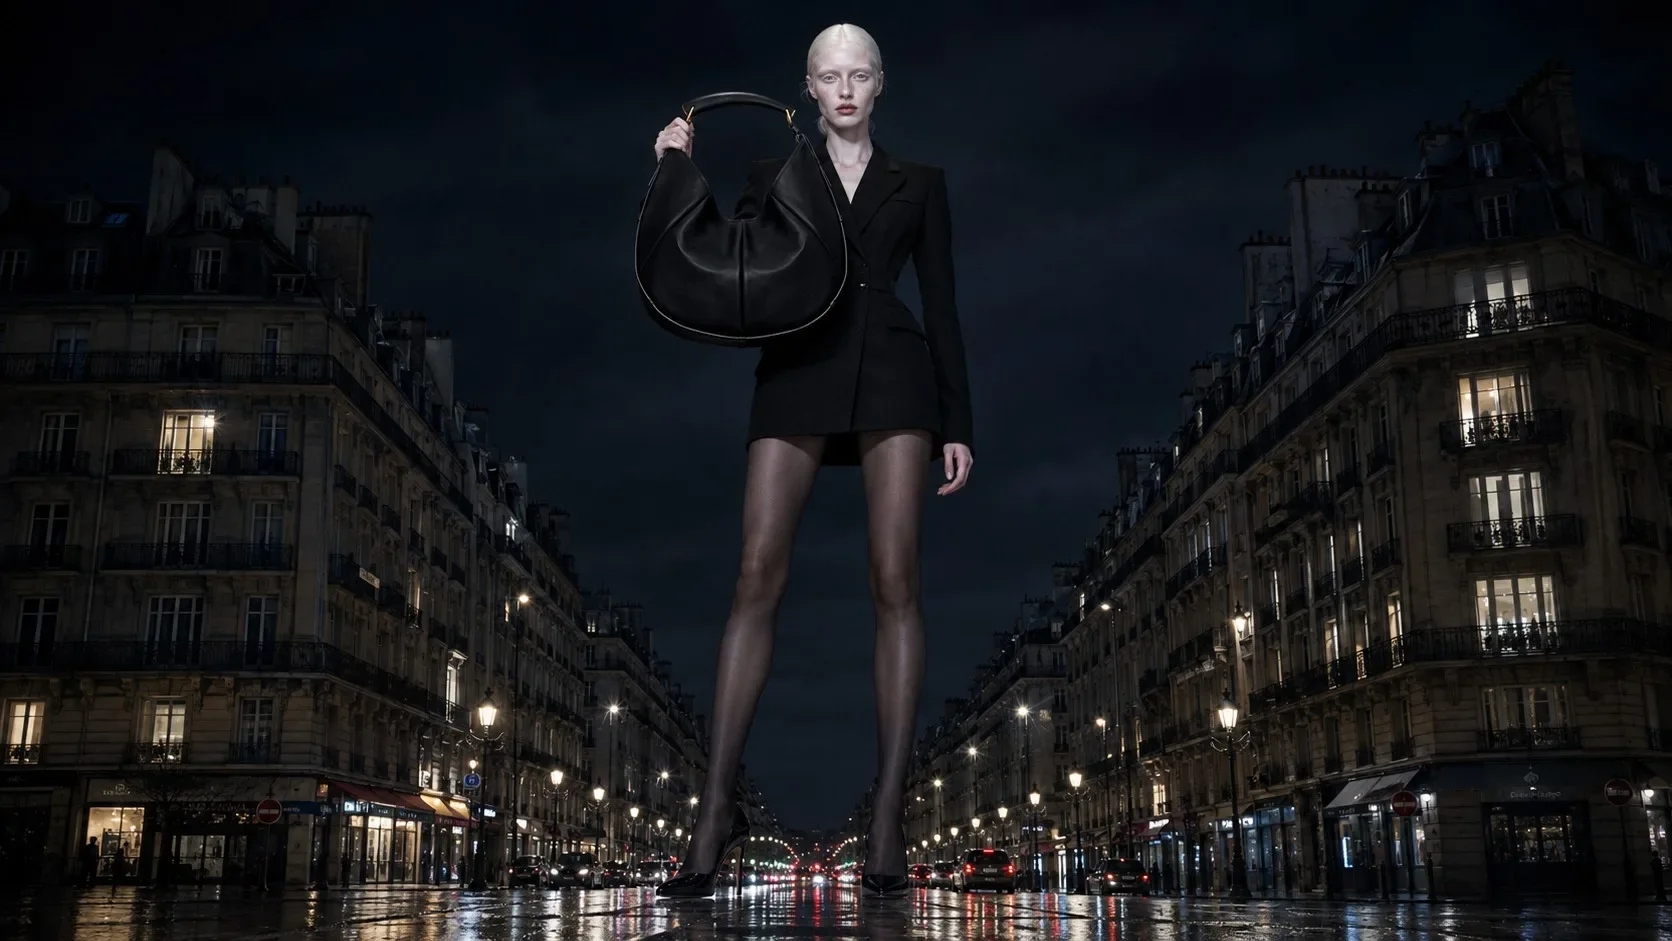
A recurring failure mode in AI production stems from expecting generative engines to reconcile physically impossible creative briefs. When our team initially staged a standard-scale model stepping across Parisian architecture, the generation repeatedly degraded into twisted hips and elongated leg geometry. The failure was not a defect in prompt syntax; it was an irreconcilable geometric conflict.
A normal human stride spans approximately 1m. A typical Parisian street separates adjacent apartment blocks by approximately 25m. Forcing an image-to-video diffusion model to animate a standard human walking across that span creates insurmountable interpolation artifacts. Because the subject cannot physically reach the opposing roof, downstream motion models hallucinate elastic limbs, mid-air leaps, or sudden teleportation.
We solved the defect upstream by altering the absolute scale of the scene. Rather than forcing an impossible stride, the talent was rendered at a colossal scale of seven storeys tall. At this scale, the 25m street gap becomes significantly narrower than the width of her shoe. A previously impossible physical leap dissolved into an effortless, casual step, allowing subsequent video synthesis to execute smoothly without requiring complex motion workarounds.
Grounding realism through unified shadow mechanics
Physical grounding cannot rely on geometry alone; it must be ratified by lighting and contact occlusion. Synthetic characters frequently look pasted onto environments because the model renders independent light paths for the subject and the terrain. To enforce physical unity, the prompt dictates coherent contact lighting.
The conditioning specifies two distinct lighting behaviors: broad cast shadows and local contact occlusion. Because the talent stands seven storeys tall above the zinc roofline, she casts a single, massive soft shadow that stretches across multiple buildings simultaneously. Locally, where the sole of her shoe meets the zinc plate, the prompt mandates deep contact shadows with visible occlusion gradients. These contact shadows anchor the footwear to the texture of the roof, eliminating the characteristic ambient glow that betrays composite generation.
Managing this complexity requires strict discipline across the reference pipeline. Our production template fixes the reference budget at exactly 5 slots: 2 facial identity frames, 1 full-body proportions frame, 1 isolated product reference, and 1 dedicated composition plate. Locking reference inputs prevents visual noise from diluting spatial conditioning, ensuring that the model maintains immaculate grounding throughout the sequence.
Related
Writing Camera Moves for AI Video Models
Naming the move, one move per shot, what models do with compound moves: camera mechanics, dialogue constraints, and previz rules.
How to Prompt Seedance 2.5 for Dialogue Scenes
Two synthetic characters, two voices, two lines — and the right mouth moved for each on the first try. The structure that made it work, and the failures that taught us each rule.
Designing Synthetic Voices: Text Descriptors Beat Voice Clones
Cloning third-party voice catalogs creates licensing ambiguity and acoustic artifacts. Designing bespoke synthetic voices from text descriptors delivers unencumbered audio.