How to Prompt Seedance 2.5 for Dialogue Scenes
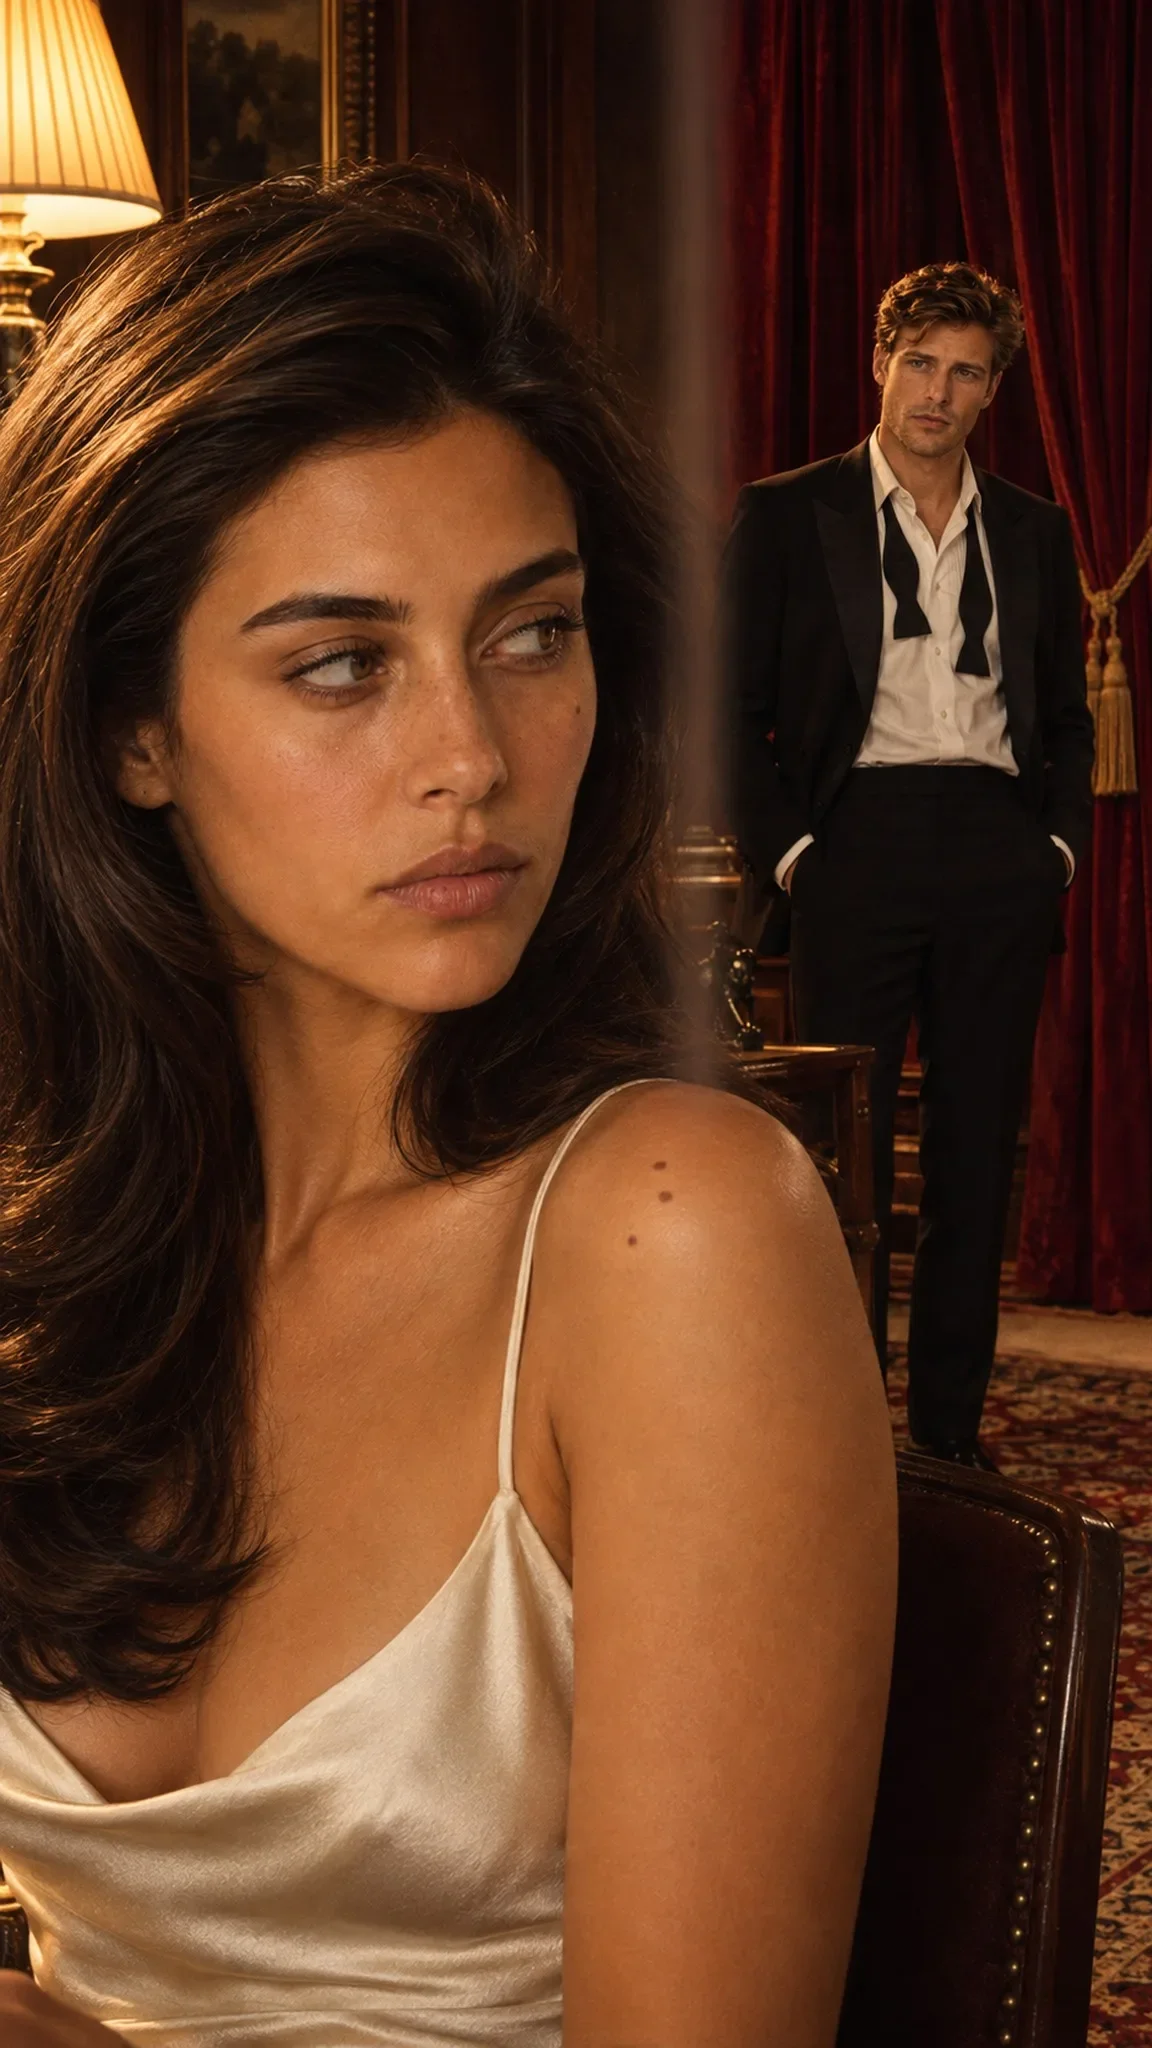
Two synthetic characters, two voices, two lines — and the right mouth moved for each on the first try. The structure that made it work, and the failures that taught us each rule.
Key takeaways
- Give every spoken line its own timestamp slice, name the speaker and the language, quote the words, and bind a voice reference to it.
- In our two-character test both lines came back word-perfect and only the speaking mouth moved — on the first render.
- A first-frame still is a hint, not a lock: describe only what moves, or the model rebuilds the room.
- Naming a prop invites the model to write on it: a 'red on-air lamp' came back with ON AIR lettering.
- Failed and blocked generations were not billed; completed 720p video cost us $0.4622 per second.
The structure that works
Seedance 2.5 handles dialogue well when every line is given its own slot. Our working form, following the official BytePlus prompting guide:
- Each spoken line gets its own timestamp slice — for example `0-1.5 seconds:` or `2.0s-5.5s:` — in chronological order.
- Inside the slice: the speaker, their image reference, the language, the delivery, then the exact words in plain double quotes. For example: `MAYA (@Image 1) says in American English, quietly and flatly: "You kept the keys."`
- After the line: `The timbre references @Audio 1.` — binding that speaker's voice reference.
- Close with `Lip movements must match the timing of the speech.`
Name the language on every line. Seedance 2.5 covers English, Spanish, Portuguese, Japanese, Korean, Arabic and several more, but not every language — Turkish, for example, is not supported, so we write lines in English.
Two faces, two voices, first try
Our most useful test was a seven-second 480p clip with two synthetic characters from separate reference sheets, two voice references and no first frame. It cost $1.44.
Both lines came back word-perfect on their slices. The right mouth moved for each line while the other stayed closed, and the characters never swapped sides.
It was not perfect. We asked for the characters' lips to stop an inch apart and they touched noses, and one character's hair came out flatter than her sheet. It was one test, so we treat it as a strong signal rather than a guarantee.
Voice references: what to record
Use one clean, noise-free clip per speaker, about five to ten seconds long. Seedance takes more than timbre from the reference — it also picks up emotion and rhythm. So record the reference in the register of the scene, and do not put the scene's actual lines in it.
In the default mode the words come from your prompt and the audio reference supplies only the voice. That has a consequence: written non-verbals disappear. A laugh, a sigh or an "um" typed into the line does not survive.
There is a second mode. When we supplied a timed speech track as the only audio reference and the prompt said only who speaks when, the speech landed on the track's timing and a transcription read the full line. The generated waveform is not identical to the track, so swap the original recording back in during the edit.
A first frame is a hint, not a lock
When we started a one-character shot from a still and mentioned where the other character stood, the model added a second person. When we re-described the room, it rebuilt a wider shot.
The wording that held: "keep the framing, background and light of @Image 1 exactly; do not add any person or object that is not in @Image 1", then "Use @Image 1 as the exact first frame and continue forward from that moment" — and after that, describe only what moves.
Small words with big side effects
- Props get labels. A "red on-air lamp" came back with ON AIR written on it. "Plain red lamp with no letters" fixed it.
- Repeating a line's distinctive phrase elsewhere in the prompt triggers subtitles. Say it once, inside its slice.
- Kill subtitles and music explicitly: "Pure video, no subtitles, no background music."
- Hands need anchors. Hands drifted below a desk until the prompt said "both hands flat on top of the desk and clearly visible, never below the desk edge." "Her right hand points to frame right" crossed her body; "the hand on the frame-right side" did not.
- Entrances need a stated hold. A character kept walking into a pan until the prompt said she "is already standing there when the pan arrives".
- Some actions win over the negative. A trumpet raised to the lips produced the note although the prompt said it was not played. Allow the action and fix the sound in post.
Resolution: 720p is a new roll
We draft at 480p and finish at 720p, but 720p is a new generation, not an upscale of the draft. A hairstyle that rendered correctly at 480p came back as a beehive at 720p from the same prompt. If a detail matters, state it firmly enough to survive a fresh roll: "shoulder-length, volume close to the head, not a beehive."
For vertical video, set the aspect in the request and write "Vertical 9:16" in the prompt. Do not generate 16:9 and crop — a vertical crop from 720p landscape is only 405×720.
Content checks and what you pay for
Close two-person framing can trip content safety. "Bare shoulder in the foreground" with an arm's-length approach was blocked twice. Removing "bare", putting two steps between the characters and framing waist-up passed first time. A repeat block on an unchanged prompt is the prompt, not bad luck.
Through the API we used, failed and blocked jobs were not billed — only completed ones. Completed video cost $0.4622 per second at 720p and $0.2056 at 480p. Repairing four seconds of a clip with video editing cost about $2.22, cheaper than re-rolling a long take.
Related
Upscaling AI Video Without Plastic Skin
The upscaler with the best sharpness score was the one a producer rejected. Here is what we tested, what each one did to faces and products, and how to check an upscale properly.
Kling 4.0 vs Seedance 2.5: Cost per Second and What Each Gets Wrong
Kling 4.0 really is less than half the price of Seedance 2.5 on the same platform. What the price comparison leaves out is the three default behaviours you have to prompt against, and the question nobody has answered yet: faces.
MiniMax H3 Needs a Schema, Not Prose
We rewrote a camera move and the walk direction and got a byte-identical video. We changed only the seed and got a different film. What H3 actually listens to, measured on a local 16 GB GPU.