
Multi-Angle AI Personas: The sks Trigger and Mirroring Rules
Paraphrasing camera angles causes multi-angle diffusion adapters to fail. How exact sks token grammar and PIL mirroring solve multi-angle talent sets.
Key takeaways
- Specialized camera adapters require strict token formatting; generic phrases like 'rotate 45 degrees' are completely ignored.
- QwenMultiangleCameraNode maps discrete degrees to rigid strings, emitting '<sks> <view> <elevation> <distance>' conditioning.
- Generative models struggle to rotate faces to steep lateral profiles while holding identity; horizontal mirroring provides flawless symmetry.
- Running Qwen-2511 GGUF (13 GB) and its vision encoder (8.7 GB) on a 16 GB GPU requires RAM offloading, taking 1 to 2 minutes on initial loads.
- Micro-scale skin realism cannot be resolved inside angle-edit models; prompt escalation yields waxy surfaces that require downstream passes.
The failure of natural language camera descriptions
Building a certified synthetic persona requires generating consistent facial angles from a single frontal master anchor. In traditional 3D software, orbiting a virtual camera around a mesh is an elementary mathematical transformation. In diffusion edit pipelines, however, camera control relies on specialized low-rank adaptation weights trained to interpret view vectors. When prompt engineers attempt to direct these models using conversational English, the conditioning routinely collapses.
During early testing of our character-sheet pipeline on 2026-06-20, automation scripts submitted descriptive natural language prompts such as 'rotate the subject to a left three-quarter view' or 'capture her profile from the side'. The model completely disregarded the directional instruction. Instead of rotating the character in three-dimensional latent space, Qwen-Image-Edit simply reproduced the frontal facing of the anchor reference, making minor adjustments to lighting while preserving the forward gaze.
Specialized camera LoRAs do not understand natural language synonyms; they respond exclusively to explicit trigger grammar. Inspecting the source code of `QwenMultiangleCameraNode` revealed that the adapter was trained on rigid, tokenized syntax. Paraphrasing the prompt stripped away the specific semantic signals required to activate the latent rotation weights, leaving the model anchored to its default perspective.
Decoding the strict output grammar of camera nodes
To achieve predictable spatial rotation, prompt pipelines must mirror the exact string emission expected by the underlying model adapter. The `QwenMultiangleCameraNode` maps geometric angular measurements into hardcoded lexical tokens. Rather than accepting continuous floating-point coordinates, the node quantizes rotation into discrete perspective buckets.
Specifically, the node enforces a strict mapping: 0 degrees corresponds to 'front', 45 degrees maps to 'front-right quarter', 90 degrees represents 'right side view', 180 degrees indicates 'back', and 270 degrees defines 'left side view'. These perspective strings are formatted into a rigid templated grammar: `<sks> <view> <elevation> <distance>`. The initial `<sks>` token acts as the primary activation gate for the fal camera LoRA.
| Angular Input | Lexical Perspective String | Synthesized Conditioning Output | Observed Camera Response |
|---|---|---|---|
| 0 degrees | 'front' | `<sks> front eye-level medium` | Locked frontal facial anchor |
| 45 degrees | 'front-right quarter' | `<sks> front-right quarter eye-level medium` | Clean 45-degree three-quarter turn |
| 90 degrees | 'right side view' | `<sks> right side view eye-level medium` | Pure lateral profile facing right |
| 180 degrees | 'back' | `<sks> back eye-level medium` | Full rear view; neckline geometry |
| 270 degrees | 'left side view' | `<sks> left side view eye-level medium` | Pure lateral profile facing left |
When prompts omit the `<sks>` prefix or replace 'front-right quarter' with colloquial phrases like 'slight turn to the right', the adapter weights remain dormant. Structuring prompts through the node's native grammar guarantees that the model shifts perspective reliably across batch iterations.
The lateral profile dilemma and the mirroring solution
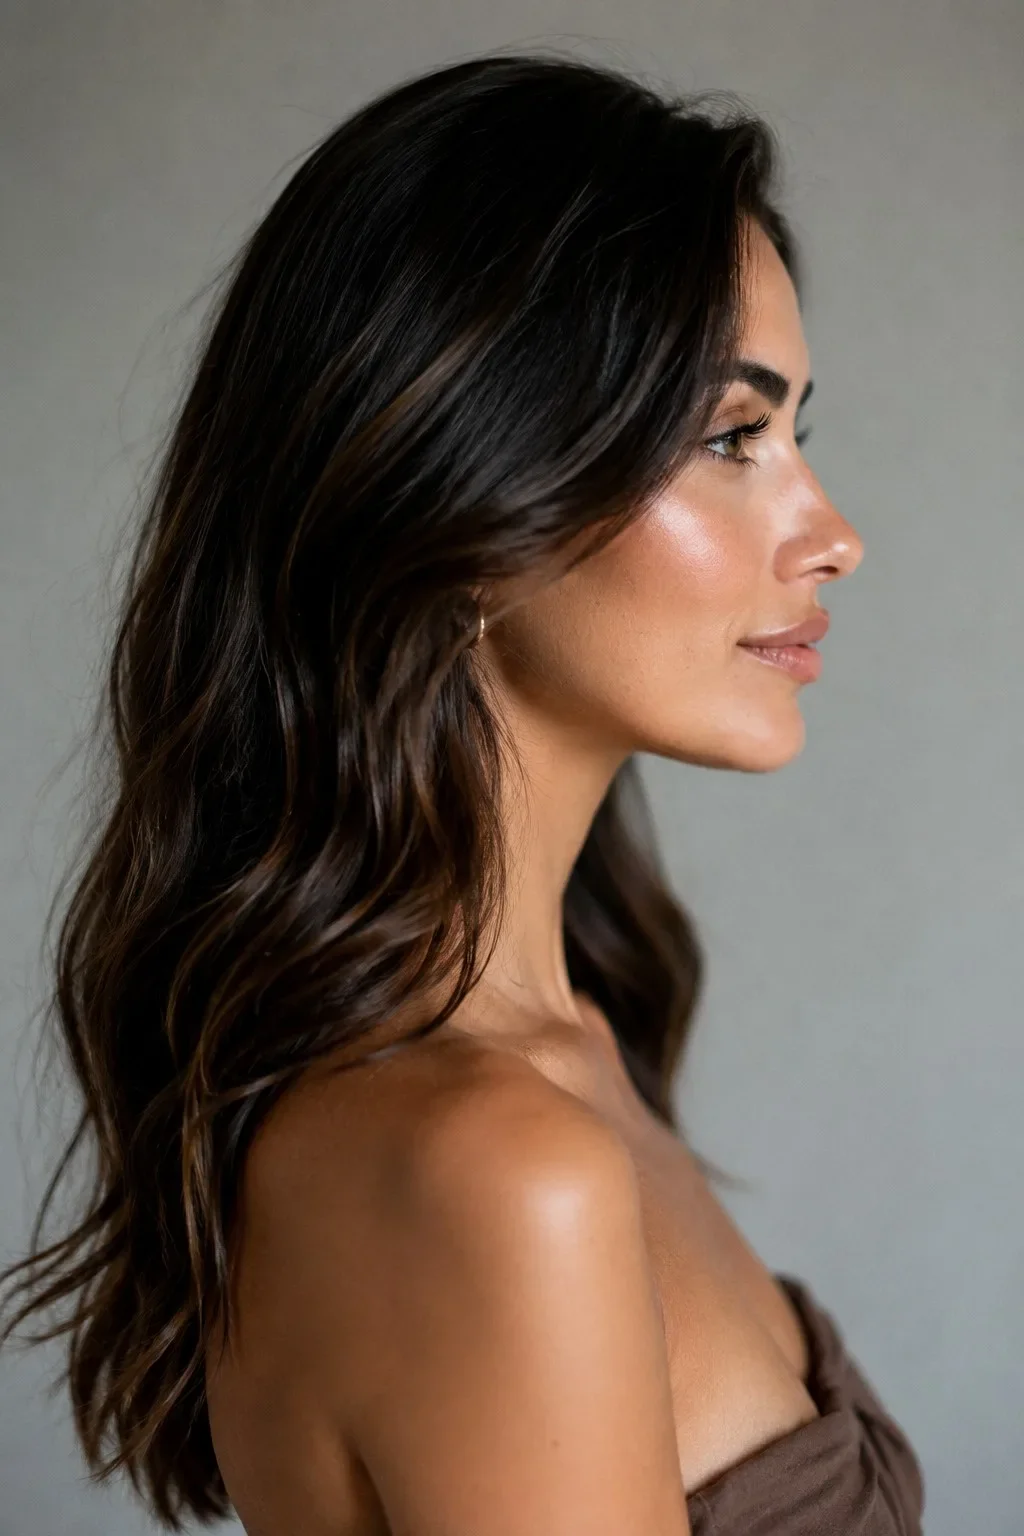
Even when conditioned with immaculate token grammar, diffusion models encounter severe architectural limitations during extreme camera rotations. Generating a true 90-degree side profile from a frontal reference requires the network to hallucinate completely occluded facial anatomy, including the bridge depth, nasal projection, and jaw angle. In our benchmarks, attempting to generate an opposing right profile from a synthesized left profile resulted in complete pipeline failure.
Across three consecutive generation attempts, the model exhibited an intractable tradeoff: it either rendered the correct right-facing direction while drifting facial identity (producing mismatched lips, altered brow thickness, and a different nose shape), or it preserved facial identity while failing to execute the 180-degree lateral flip. The generative engine could not simultaneously maintain identity coherence and invert the structural orientation.
We solved this dilemma by bypassing generative synthesis entirely. Applying PIL FLIP_LEFT_RIGHT horizontal mirroring to the validated left profile produced a geometrically perfect right profile. The transformation preserves craniofacial identity down to the pixel level. While mirroring inverts asymmetrical attributes like hair parts or small earrings, these micro-variations are completely irrelevant for dataset training. The LoRA learns fundamental facial bone structure, making geometric mirroring vastly superior to generative guessing.
Hardware memory offloading across Qwen GGUF weights
Executing multi-angle character editing on local developer workstations requires managing extensive neural network weights within consumer hardware budgets. The local pipeline couples the Qwen-2511 GGUF base model measuring 13 GB with its accompanying Qwen-VL vision encoder measuring 8.7 GB. Attempting to fit both uncompressed models simultaneously into dedicated VRAM immediately breaches the 16 GB hardware ceiling.
The system resolves memory pressure through dynamic system RAM offloading. When initialized inside ComfyUI, the inference engine loads the vision encoder into host memory while streaming active layers into GPU memory during execution. During initial model loading and first inference passes, dedicated GPU memory pins at approximately 95% utilization, requiring 1 to 2 minutes to complete the first frame.
Developers frequently mistake this initial memory saturation for a system crash. System monitoring tools report maximum memory consumption while terminal output pauses during weight transfer. Once the pipeline completes its initial warm-up pass, subsequent angular iterations execute steadily without memory thrashing, proving that consumer workstations can support complex multi-model pipelines when memory offloading is properly configured.
Decoupling angular synthesis from surface photorealism
A critical strategic insight gained during character sheet development is that generative models should not be forced to solve multiple technical problems simultaneously. In early pipeline iterations, engineers attempted to force Qwen-Edit to produce high-resolution skin realism alongside camera rotations by injecting extensive photographic terminology: pores, skin texture, DSLR lenses, and anti-smoothing exclusions.
The resulting imagery showed negligible improvement. Visual evaluations confirmed that the output retained a waxy, cosmetic-render appearance regardless of prompt complexity. Qwen-Edit is fundamentally an editing model optimized for spatial transformation and structural coherence; it lacks the fine-grained texture synthesis of dedicated diffusion models.
Recognizing this structural limitation, our studio decoupled camera rotation from surface realism. Qwen-Edit is tasked solely with establishing accurate camera angles, bone structure, and gaze directions. Once clean multi-angle character anchors are captured, the entire image set passes into a downstream realism pipeline. Decoupling spatial rotation from texture synthesis allows each neural model to operate within its optimal capability envelope.
Related
Writing Camera Moves for AI Video Models
Naming the move, one move per shot, what models do with compound moves: camera mechanics, dialogue constraints, and previz rules.
How to Prompt Seedance 2.5 for Dialogue Scenes
Two synthetic characters, two voices, two lines — and the right mouth moved for each on the first try. The structure that made it work, and the failures that taught us each rule.
Designing Synthetic Voices: Text Descriptors Beat Voice Clones
Cloning third-party voice catalogs creates licensing ambiguity and acoustic artifacts. Designing bespoke synthetic voices from text descriptors delivers unencumbered audio.