Transparent-Background AI Images: Real Alpha, Not a Cutout
Native alpha vs background removal: Qwen-Image 2.1 delivers real RGBA transparency, measured performance, and its strict research-only licence.
OMNI LabsUpdated
Key takeaways
Qwen-Image 2.1 outputs a native RGBA alpha channel with 34.3% transparent pixels (alpha <= 5) and 62.0% solid pixels.
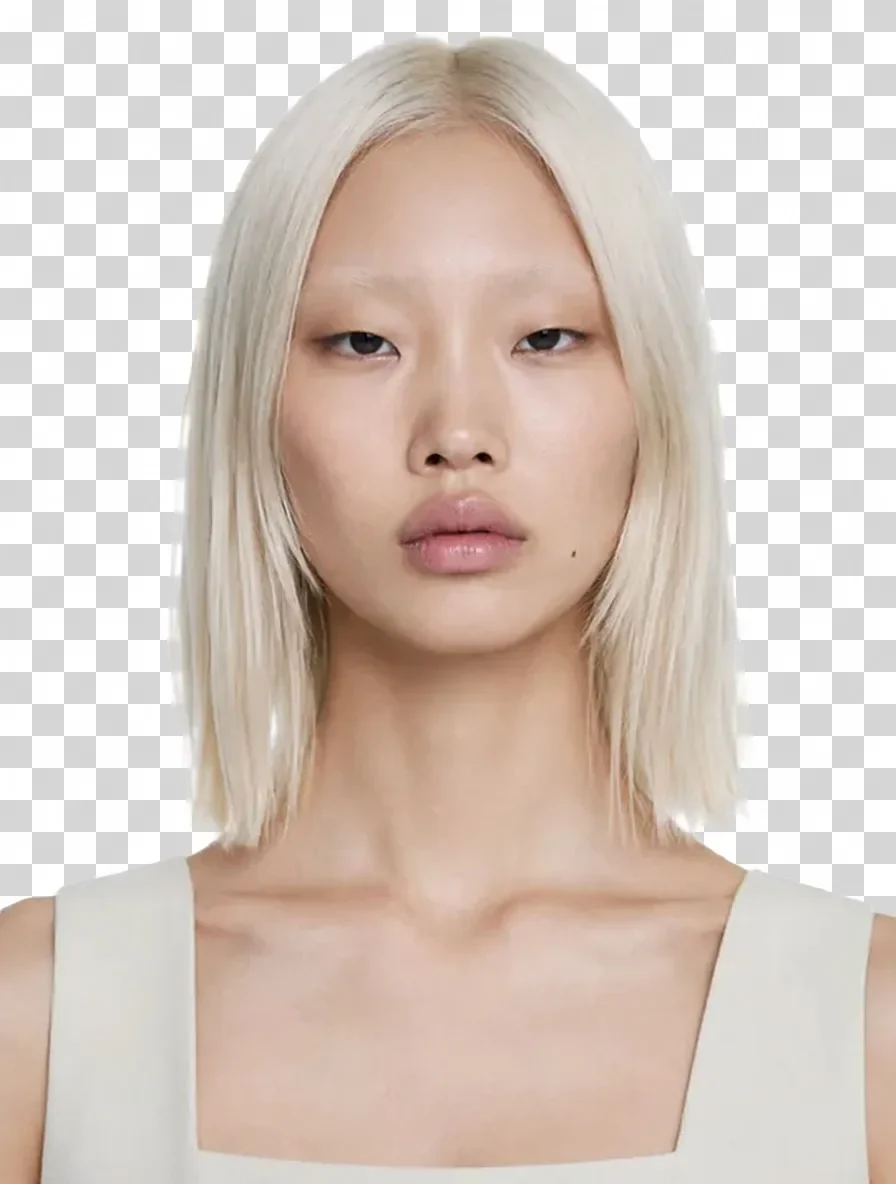
True alpha generation delivers clean fine hair strands with zero edge halo, requiring explicit cutout prompt templates.
A warm alpha cutout requires about 90 seconds on an RTX 5060 Ti 16GB, compared to 68 seconds for 1024 text-to-image.
Qwen-Image 2.1 carries a strict research-only licence forbidding commercial delivery; commercial work routes to FLUX klein.
Text encoder selection dictates latency: w4a8 completes in 102.1 s versus 170.2 s for stock int8 (+67% slower).
Native RGBA transparency versus post-hoc background removal
Qwen-Image 2.1 returns a real RGBA alpha channel from its background-removal template. Our measured cutout on an RTX 5060 Ti 16GB came out with 34.3% of pixels at alpha 5 or below, 62.0% at alpha 250 or above, and 3.0% feathered, with clean hair edges and no white halo.
In graphic design and 3D asset pipelines, isolating subjects with transparent backgrounds historically required secondary segmentation filters. Post-hoc background matting tools frequently leave unsightly edge halos, erase semi-transparent wisps of hair, and struggle with complex textile weaves. In contrast, Qwen-Image 2.1 integrates transparent alpha emission directly into its diffusion generative process. Evaluating the background-removal template on a local RTX 5060 Ti 16GB workstation produced an authentic four-channel RGBA file: 34.3% of canvas pixels measured at alpha 5 or below (complete transparency), 62.0% measured at alpha 250 or above (full opacity), and 3.0% formed a delicate feathered transition zone that preserved fine blonde hair strands without perimeter halos.
Alpha is emitted only when the job asks for it. A normal Qwen edit on the same input came back 100% opaque, so the cutout must be requested explicitly.
Native transparency is not an automatic diffusion default. Submitting standard editing prompts without configuring the specialized background-removal template yields a standard 100% opaque RGB image. Production workflows must explicitly route jobs through the designated transparency template to trigger alpha channel synthesis.
Inference latency and the strict research-only licence boundary
A warm alpha cutout took about 90 seconds on our card, against about 68 seconds for a warm 1024 text-to-image.
Generating dual-domain color and transparency data introduces computational overhead. On our 16GB test GPU, synthesizing a warm RGBA cutout required approximately 90 seconds, compared to 68 seconds for standard 1024 text-to-image inference. The additional latency represents the extra compute required to denoise the fourth channel simultaneously.
The licence is qwen-research: no commercial use. We use Qwen 2.1 for spec work, concepts, roster stills, cutout compositing layers and internal QA only. Client and sold delivery go to FLUX klein, which is Apache-2.0 and has no alpha output.
Legal compliance dictates rigid pipeline routing. Qwen-Image 2.1 is distributed under the proprietary qwen-research licence, strictly prohibiting commercial deployment. In our studio operations, Qwen 2.1 is restricted to internal spec presentations, creative ideation, roster prototyping, compositing mockups, and internal quality audits. For commercial client deliverables, our production stack routes generation to FLUX klein, an Apache-2.0 open-weights foundation model that provides clean IP clearance despite lacking native alpha channels.
Encoder optimization: w4a8 acceleration
The Qwen text encoder matters for speed: in our 25-step test the w4a8 encoder took 102.1 seconds, while the int8 encoder that the stock workflows default to took 170.2 seconds (+67%) on this 16GB card. A warm 1024 text-to-image takes about 68 seconds.
Text encoder quantization heavily impacts local workstation throughput. In a 25-step benchmark on our 16GB card, deploying the w4a8 quantized text encoder concluded inference in 102.1 seconds (102.1 s). In contrast, the stock int8 encoder bundled in standard community workflows required 170.2 seconds (170.2 s)—an increase of 67% (+67%) in total runtime. Selecting w4a8 quantization is critical for maintaining workable local iterations.
Reference-key and memory traps, with the numbers in one table
Qwen-Image 2.1 transparency performance, encoders, and hardware boundaries · measured 2 Oct 2026
Configuration / Pipeline Component
Workstation Hardware Setting
Benchmark Latency / Metric
Studio Operational Policy
Native RGBA Alpha Cutout
RTX 5060 Ti 16GB (warm)
~90 seconds (vs 68 s standard 1024)
34.3% alpha <= 5, 62.0% >= 250, 3.0% feathered
Quantized Text Encoder (w4a8)
25-step test on 16GB card
102.1 seconds
Recommended local production configuration
Stock Text Encoder (int8)
25-step test on 16GB card
170.2 seconds (+67% slower)
Default workflow; rejected for severe latency
Reference Image Input Key
ComfyUI node wiring
images.image_1 (mandatory)
Plain 'images' key silently drops reference
Reference Memory Ceiling
16GB local VRAM limit
Maximum 3 references
4th reference triggers text encoder OOM crashes
Post-Hoc 3D Segmentation
rembg (isnet-general-use)
Alpha matting post-process
Mask estimated after the fact for 3D meshes
Measured on 2026-10-02; Qwen-Image 2.1 governed strictly by qwen-research licence.
Wiring trap: the reference image input key is images.image_1, not images. A plain images key is silently dropped, and the output is a convincing image of a different person. The tell is an edit that runs faster than plain text-to-image.
Node integration requires strict parameter naming. In automated ComfyUI graphs, the reference image connector must be declared as images.image_1. Passing a generic 'images' key causes the model to silently discard the reference input without error, generating an unrelated face. Engineers can detect this failure when an edit job executes abnormally fast, matching unconditioned text-to-image speeds.
Alternative 3D workflows, memory ceilings, and canvas ratios
For our 3D pipelines we cut RGBA images with background removal instead: rembg with the isnet-general-use model and alpha matting, output with a transparent background. That is a mask estimated after the fact, not alpha the generator produced.
When commercial 3D asset generation mandates Apache-2.0 compliance, pipelines utilize post-process segmentation rather than research-only models. In these workflows, clean RGB renders from FLUX klein pass through rembg using the isnet-general-use model with alpha matting enabled. While this creates a post-hoc transparency mask rather than natively synthesized alpha, it maintains strict legal clearance.
The 3-reference ceiling is the 16GB limit on this card, not the advertised 10; a fourth reference ran out of memory in the text encoder and the runner refuses it.
Hardware boundaries override theoretical framework limits. Although documentation claims support for up to 10 image references, local 16GB hardware imposes a hard ceiling of three references. Loading a fourth reference triggers an immediate out-of-memory crash in the text encoder, prompting our automated runner to reject four-reference requests.
Qwen 2.1 edits follow the reference aspect ratio and ignore the resolution setting, so plan the cutout canvas from the source image before the job.
Canvas sizing enforces reference adherence. Qwen-Image 2.1 locks internal aspect ratios to the input reference image, disregarding external resolution arguments. Production teams must crop source reference plates to intended aspect dimensions prior to dispatching transparency jobs.